01
Faster, cheaper inference is how access grows
Every time a model gets faster and a token gets cheaper, more people can build with intelligence. Pushing both is the work we care about most.
About RunAnywhere
That is our mission, in the words of our CEO, Sanchit Monga. In practice it means faster, cheaper inference: the best open models, quick and affordable for anyone who builds with them.
Our story
Sanchit and Shubham meet as students at RIT.
We start RunAnywhere to run AI on the devices people already own.
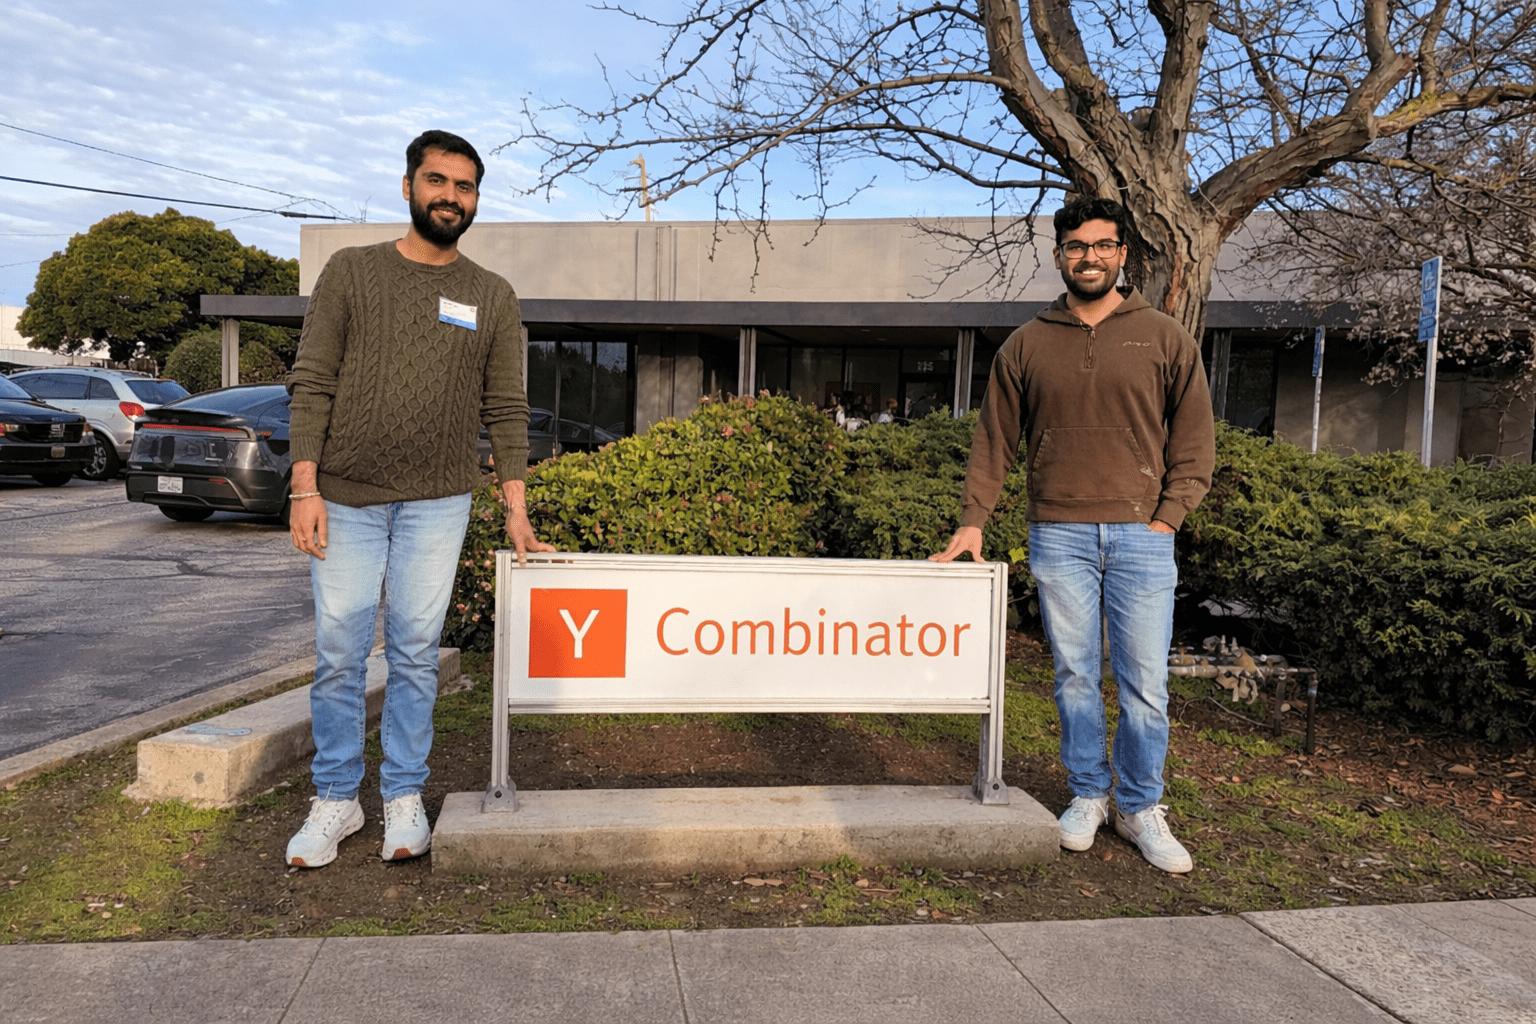
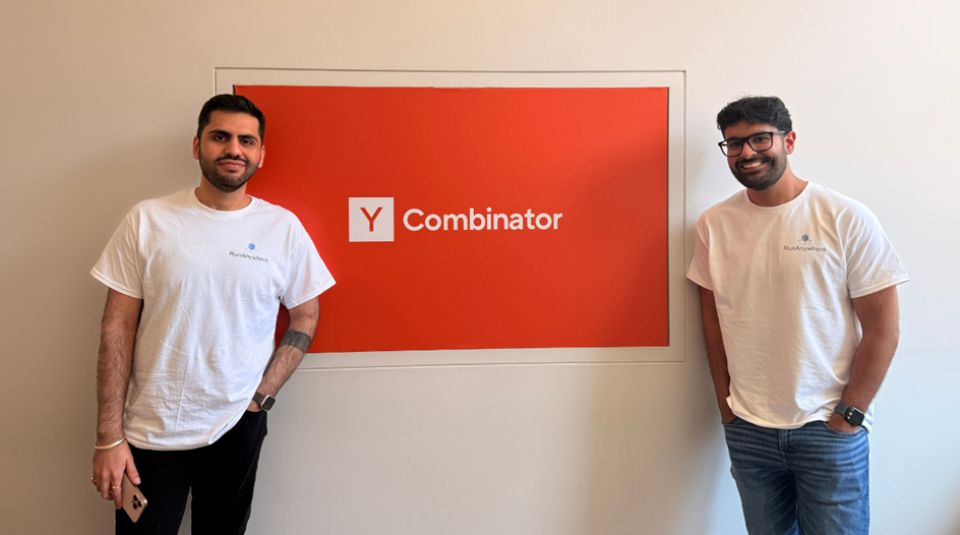
We go through Y Combinator and open-source the RunAnywhere SDKs.
Our AI agents build engines for the Apple Neural Engine and Qualcomm Hexagon NPUs, and we publish every result with its method.
The models people want no longer fit on a phone or a laptop, so we launch Wally to host frontier open models.
Wally's catalog grows to ten models, with fast versions for agent loops.
What we believe
01
Every time a model gets faster and a token gets cheaper, more people can build with intelligence. Pushing both is the work we care about most.
02
Speed and cost are decided by the kernels and the serving stack. Our AI agents build them end to end, and every result is checked on the hardware it runs on.
03
Every result we publish names its model, workload, hardware and date, with the data behind it. If a number changes, we correct it in public.
Founders
Sanchit built mobile apps and SDKs at Intuit before starting RunAnywhere. He leads product, Wally and the company.
Shubham worked on infrastructure at Microsoft Azure and AWS. He leads the serving platform and the engine work.
A small team of engineers works with them, directing the AI agents that build the kernels and the serving stack, and shipping the console and the SDKs.
Press
Most of this coverage is from early 2026, when our work was on-device inference. Our own announcements are on the blog.
 NextTech Today · March 9, 2026Regulated Industries Are Rewriting Their AI ArchitectureRegulated industries across healthcare, financial services, and telecommunications are fundamentally rethinking how they deploy AI. Rather than relying on cloud-based solutions that promise scalability, these organizations are prioritizing control and compliance, moving inference operations from centralized cloud environments to edge devices where data never leaves the premises.Read the article (opens in a new tab)
 TechBullion · March 9, 2026RunAnywhere Is Building the Infrastructure Layer for On-Device AI at ScaleRunAnywhere, a Y Combinator-backed startup founded by Sanchit Monga and Shubham Malhotra, is building the infrastructure to deploy AI directly on consumer and enterprise devices rather than relying on cloud servers. The founders identify a critical gap in current AI deployment: cloud-first models excel in demonstrations but struggle with real-world constraints including latency, privacy vulnerabilities, connectivity issues, and escalating cloud expenses. Their philosophy is clear: "Latency is a feature. Privacy is a feature. Reliability is a feature."Read the article (opens in a new tab)
 CEOWORLD Magazine · March 6, 2026Why the Next Wave of AI Will Run on Your PhoneIn this CEOWORLD Magazine feature, RunAnywhere founders Sanchit Monga and Shubham Malhotra make the case for why AI's future lives on smartphones and edge devices, not in the cloud. As they explain, "Models are getting smaller and faster, but deployment is still broken. That's the layer we're focused on fixing." The article explores how current AI deployment faces significant friction from high latency, unreliable connectivity, privacy concerns, and escalating cloud compute expenses that limit practical AI applications in real-world products.Read the article (opens in a new tab)
 International Business Times · March 6, 2026RunAnywhere: The Infrastructure Powering the Edge AI EraThe International Business Times profiles RunAnywhere's production-ready SDK that enables enterprises to execute AI models directly on edge devices (smartphones, IoT hardware, and existing CPUs/GPUs) rather than routing requests through costly cloud APIs. The article highlights a striking economic reality: only a small percentage of the global population actively uses AI tools today, and cloud-based inference costs of $0.30 to $0.50 per minute for voice AI and vision-language models make scaling to mass adoption prohibitively expensive.Read the article (opens in a new tab)
 DNA India · March 2, 2026Why India's AI Future Will Be Built on the EdgeDNA India explores how India is uniquely positioned to lead in distributed AI infrastructure by leveraging its billion-plus smartphone ecosystem as edge compute nodes, bypassing the need for expensive centralized cloud systems. The article highlights three competitive advantages: massive scale with over one billion devices, deep technical talent, and a pragmatic approach to cost-efficient AI deployment. With cloud-based multimodal and voice APIs costing $0.30 to $0.50 per minute, expanding AI access to hundreds of millions of Indian users through cloud infrastructure alone is economically unfeasible.Read the article (opens in a new tab)
 Y Combinator · January 22, 2026RunAnywhere (YC W26) helps apps run AI directly on phones and other edge devicesY Combinator highlights RunAnywhere as part of its Winter 2026 batch, showcasing the platform's ability to help apps run AI directly on phones and other edge devices. The post emphasizes RunAnywhere's streamlined approach to on-device AI deployment: developers can integrate the SDK with minimal setup and immediately begin executing chat and voice processing locally on user devices.Read the article (opens in a new tab)
 FoundersBrief · January 16, 2026From Small-Town Punjab to YC: How Sanchit & Shubham Are Building RunAnywhere to Put AI on Every DeviceFoundersBrief profiles the journey of Sanchit Monga and Shubham Malhotra, from small-town Punjab to Y Combinator, and their mission to democratize AI by putting it directly on every device. The founders recognized that while powerful AI models were becoming smaller and more efficient, the tools for deploying them to real devices remained fragmented, complex, and inaccessible to most developers. RunAnywhere was born from the conviction that on-device AI shouldn't require months of specialized engineering.Read the article (opens in a new tab)

